n8n HTTP Request Node: Complete Documentation Guide
The HTTP Request node is how n8n talks to almost any API. This guide explains its settings in plain language, with working patterns for GET and POST requests, authentication, and handling the responses you get back.
This n8n http request node documentation explains how to use the node in real workflows, from its core settings to authentication, pagination, and troubleshooting.
If you have built anything in n8n beyond the simplest automation, you have probably run into the same wall: the service you want to connect to has no dedicated n8n node, or its node does not cover the one action you need.
That is exactly the gap the HTTP Request node exists to fill. It is the general-purpose tool in the n8n toolbox, the one that lets a workflow talk to practically any web service with an API, whether that service is a household name or a small internal tool your company runs.
That generality comes with a trade-off. Dedicated nodes hide the details of an API behind friendly fields — “list contacts”, “send message” — while the HTTP Request node asks you to supply those details yourself: the method, the URL, the headers, the authentication, and what to do with the response.
None of that is difficult once you have seen it done a few times, but the first encounter can feel like being handed a blank form when you were expecting a menu. This guide is the walkthrough that makes the blank form feel manageable: what each setting does, which ones matter for ordinary use, and the patterns that cover most real workflows.
You do not need to be a developer to use this node well, but you do need to be comfortable reading a little API documentation for the service you are connecting to. The HTTP Request node does not know what a given API expects; it faithfully sends whatever you configure.
So the skill here is less about n8n itself and more about translating an API’s documentation into the node’s fields — and that is a skill that transfers to every API you will ever connect.
What the HTTP Request Node Is For
This n8n http request node documentation begins with what the node is for and when to reach for it.
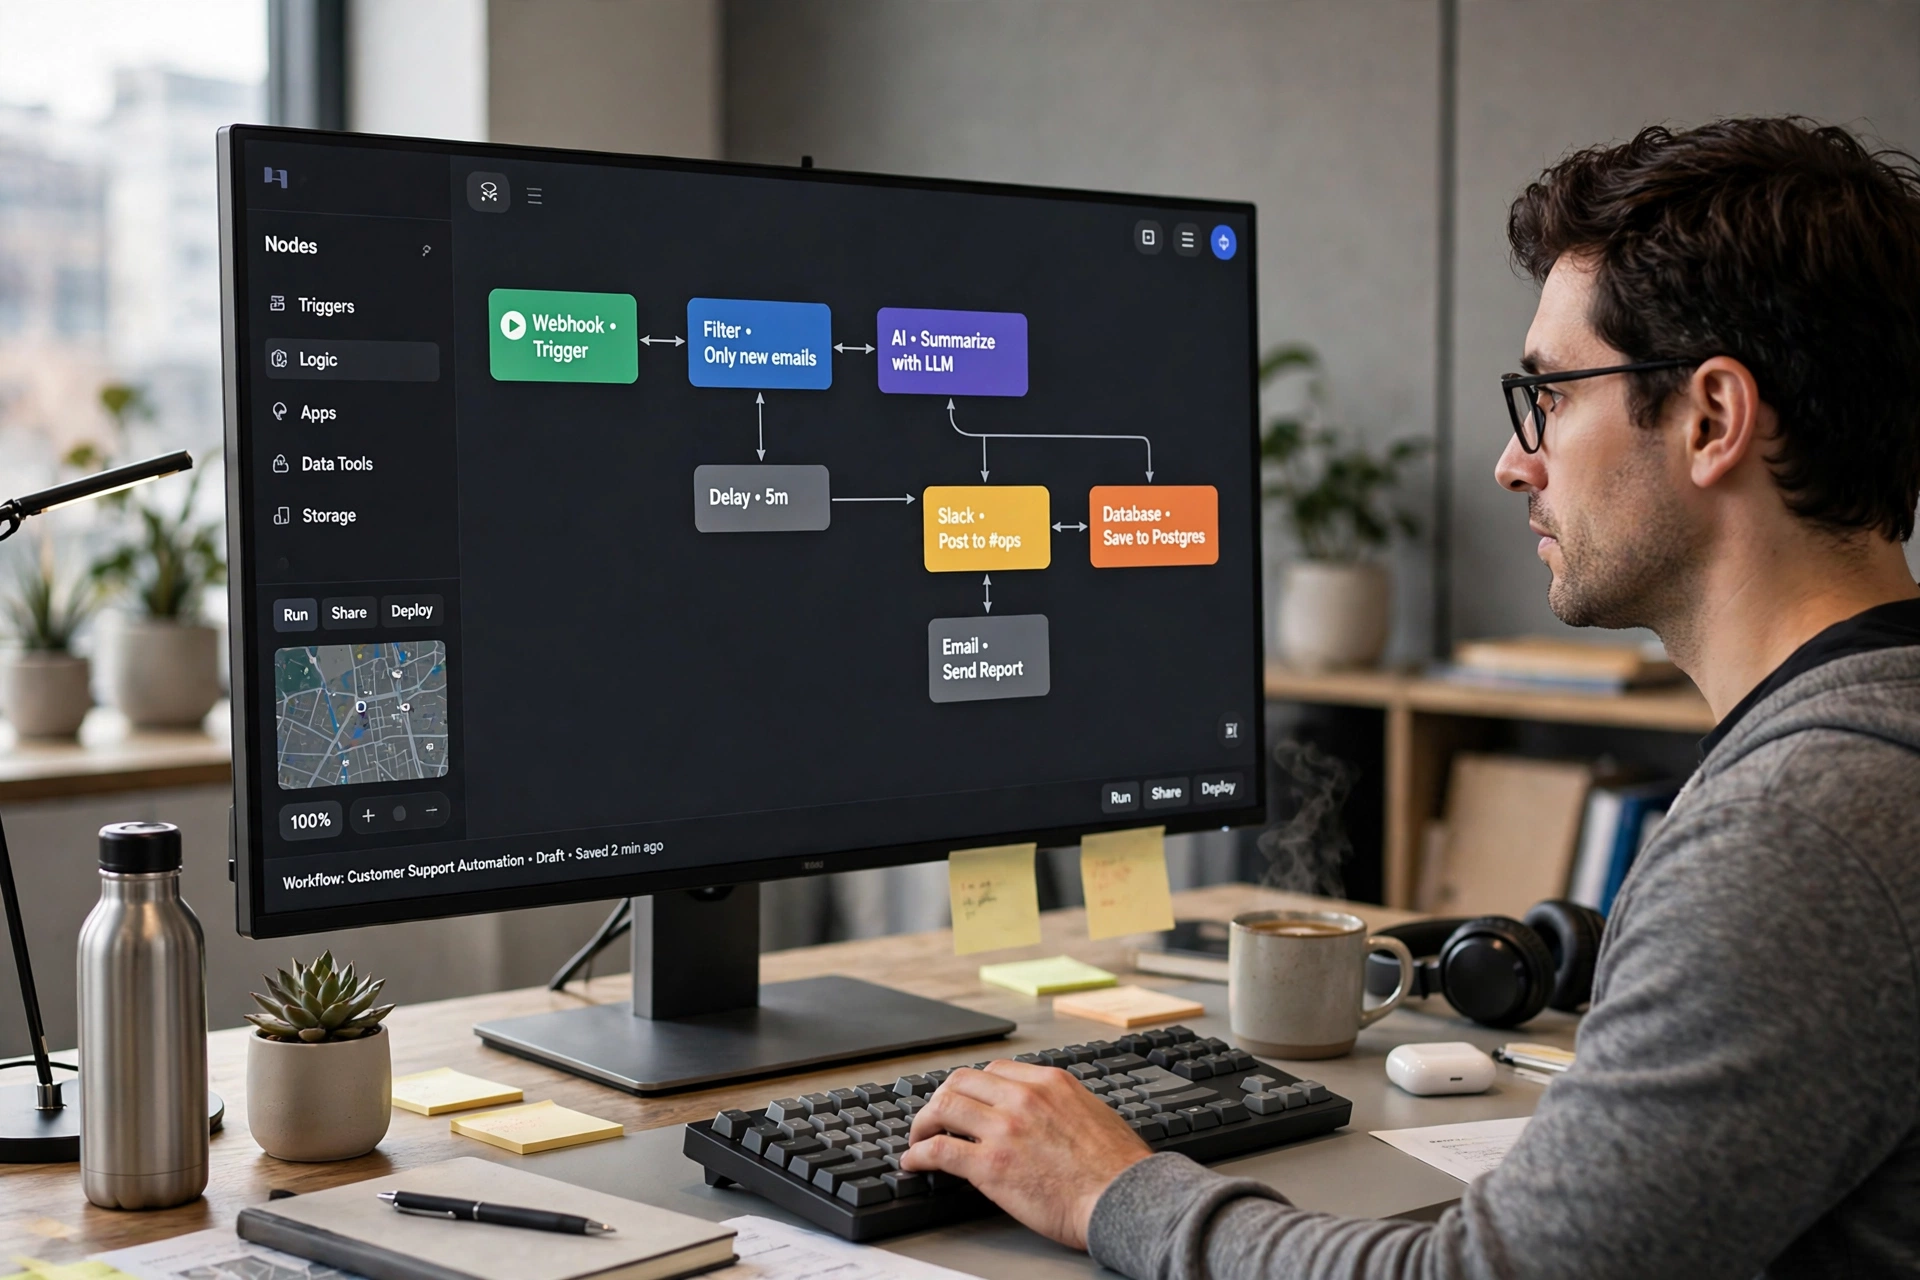
n8n is a workflow automation tool built around nodes: each node performs one step, and data flows from node to node along the connections between them. Most nodes wrap a specific service — sending an email, reading a spreadsheet, posting to a chat app.
The HTTP Request node is different: it wraps the HTTP protocol itself, which is the language almost all web APIs speak. Give it a URL and a method, and it will make a request to that URL and hand the response to the next node in the workflow.
Key: HTTP Request node — A general-purpose n8n node that sends an HTTP request to any URL and returns the response as data for the next node, used when no dedicated node exists for the service or action you need.
Key: API — An application programming interface: a documented way for one piece of software to ask another for data or actions over the web, usually using HTTP requests and JSON responses.
Key: Endpoint — A specific URL on an API that performs one job, such as listing items, fetching one item, or creating a new one.
Reach for the HTTP Request node when the service you need has an API but no dedicated n8n node, when a dedicated node exists but lacks the action you need, or when you are working with an internal or lesser-known API that will never get a dedicated node.
It is also the right choice when you need precise control over a request — a custom header, an unusual method, a particular body format — that a friendly wrapper would hide from you.
The flip side is worth stating plainly: if a good dedicated node exists for what you want, use it first. Dedicated nodes handle authentication quirks, pagination, and error cases for that service, and they will usually save you time.
The HTTP Request node is the power tool you bring out when the friendly tool does not fit, not the default for every job.
The Core Settings, in Plain Language
In this n8n http request node documentation, the core settings are explained in plain language.
Method: what you are asking the server to do
The method is the verb of the request. GET asks for data without changing anything, and it is the method you will use most often when fetching information. POST sends data to create something new.
PUT and PATCH update something that already exists, with PUT typically replacing it and PATCH typically changing part of it. DELETE asks for something to be removed.
Choosing the right method matters, because an API will reject a request that uses the wrong verb for an endpoint, even if everything else is correct. As this n8n http request node documentation shows, the API’s documentation for the endpoint you want will always state its method; match it exactly.
URL: where the request goes
The URL is the endpoint’s address, sometimes with a variable part. A request to list items might go to an address ending in /items, while a request for one specific item might go to /items/123, where 123 is the item’s identifier.
In n8n, you can build URLs dynamically using data from earlier nodes — for example, inserting an ID that a previous node fetched — which is how a workflow moves from “get the list” to “get each item in the list” without hard-coding anything.
Authentication: proving the workflow is allowed in
Almost every real API requires authentication, and getting this part right is where most first attempts stumble. The common forms are: an API key sent in a header or as a query parameter; basic authentication with a username and password; OAuth2, where n8n manages tokens on your behalf after you connect an account; and bearer token, where a token is sent in an Authorization header.
The API’s documentation will say which form it expects and where the key or token goes, and n8n’s credential system lets you store these securely rather than pasting secrets directly into the node.
This n8n http request node documentation recommends storing credentials in n8n credentials, not in visible fields. Never put a live API key into a screenshot, a shared workflow export, or a public example — credentials belong in n8n credentials, not in the workflow’s visible settings.
| Authentication type | How it is usually sent | When you will meet it |
|---|---|---|
| API key | Header or query parameter | Many public and SaaS APIs |
| Basic auth | Username and password encoded in the Authorization header | Older or simpler APIs, internal tools |
| Bearer token | Authorization header with a token | Modern APIs, often after a login or token endpoint |
| OAuth2 | Tokens managed by n8n after connecting an account | Google, Microsoft, and similar major services |
Sending Data: Parameters, Headers, and Body
In this n8n http request node documentation, sending data covers query parameters, headers, and body formats.
Query parameters
Query parameters are the key-value pairs after the question mark in a URL, and they are how you filter, sort, or page through results: asking for a particular status, a search term, or page two of a list.
In the HTTP Request node you can add them as structured fields rather than hand-building the URL string, which keeps things readable and avoids mistakes with encoding special characters.
If an API’s documentation shows an example URL with ?status=active&limit=50, those are two query parameters, and entering them as fields produces exactly that URL.
Headers
Headers are metadata sent with the request: information about the request itself rather than the data it carries. The most common ones you will set are Content-Type, which tells the server what format the body is in — usually application/json — and Accept, which says what format you would like back.
Authentication headers, such as an Authorization header carrying a bearer token, are also headers. You rarely need to set exotic headers; when an API requires a specific one, its documentation will name it, and you add it as a name-value pair in the node.
Body formats
When a request needs to send data — creating a record, updating a field, submitting a form — that data goes in the body. The most common format by far is JSON, a structured text format that looks like nested key-value pairs and is the native language of most modern APIs.
Form data is the older alternative, used by APIs that mimic a web form submission. Binary data covers file uploads.
In n8n, you typically choose JSON and either build the body with fields or write the JSON yourself, pulling values from earlier nodes where the data needs to be dynamic.
The habit to build early is checking what the API expects for each field: a number where you sent text, or a missing required field, is a very common cause of a rejected request.
Understanding the Response
In this n8n http request node documentation, understanding the response starts with status codes and response formats.
A successful request returns a status code, headers, and usually a body. The status code is the quickest summary of what happened: codes in the 200 range mean success, with 200 itself the most common; the 400 range means the request had a problem, such as bad credentials (401), forbidden access (403), a missing resource (404), or invalid data (422); and the 500 range means the server itself had a problem.
When a request fails, read the status code first, then the response body, because APIs usually include a human-readable error message there that says what was wrong far more precisely than the code alone.
The response body is usually JSON, and n8n parses it into structured data that later nodes can use. That is where the real power of the node shows up: a workflow can fetch a list of orders, loop over them, filter the ones that meet a condition, and pass each one to another node that does something with it.
If the response is not JSON — plain text, HTML, or a file — n8n can still handle it, but you may need to adjust how the node treats the response, or use a later node to extract what you need.
Key: Status code — A three-digit number in an HTTP response summarising the outcome: 2xx for success, 3xx for redirection, 4xx for a problem with the request, 5xx for a problem on the server.
Key: JSON — JavaScript Object Notation, a lightweight text format for structured data, used by most web APIs for both requests and responses.
Pagination, Rate Limits, and Large Responses
In this n8n http request node documentation, pagination, rate limits, and large responses are covered together.
Real APIs rarely hand you everything in one response. When a list has hundreds or thousands of items, the API typically returns it in pages — say, fifty at a time — with information about how to ask for the next page, either a page number, an offset, or a cursor token.
Handling this in n8n usually means looping: fetch a page, process its items, check whether another page exists, and repeat until the API says there is no more. The API’s documentation will describe its pagination method, and the HTTP Request node can be combined with loop and condition nodes to walk through pages until done.
Rate limits are the other practical constraint. Many APIs cap how many requests you may make in a given period, and exceeding that cap produces a 429 response — too many requests — often with a hint about when to retry.
A workflow that hammers an API without pauses will hit this wall, so for bulk work it is sensible to add small waits between requests, or to process items in batches. This n8n http request node documentation notes that respecting rate limits is not just polite; it keeps the workflow from being blocked partway through a large job.
Large responses deserve a thought too. Fetching a huge dataset into a workflow in one go can be slow and memory-hungry. Where an API supports filtering or field selection, use it: ask for only the records and fields the workflow actually needs, rather than pulling everything and discarding most of it downstream. It makes the workflow faster, cheaper to run, and easier to debug.
Error Handling in a Workflow
In this n8n http request node documentation, error handling is treated as a core part of a reliable workflow.
A workflow that assumes every request succeeds will break the first time an API is slow, a token expires, or a record is missing. The HTTP Request node lets you decide what happens on a failed response: whether the workflow stops, or continues with the error available to later nodes so you can log it, retry it, or route it to a fallback step.
For anything that runs unattended — a nightly sync, a scheduled import — building in that tolerance is not optional polish, it is the difference between a workflow that quietly recovers and one that silently stops halfway through its job.
A practical pattern is to treat different failures differently. A 404 for one item in a list may be fine to skip and log, while a 401 across the board means the credentials need attention and the workflow should alert someone rather than retrying forever.
A 429 usually means “slow down and retry shortly”, while a 500 may mean “try again later”. Encoding even a simple version of that logic — retry once after a short wait for transient errors, log and continue for missing items, stop and alert for authentication failures — makes a workflow dramatically more reliable in production.
Practical Patterns You Can Reuse
In this n8n http request node documentation, the practical patterns below can be reused across workflows.
Pattern 1 — Fetch and filter
Fetch a list with a GET request, then use a filter or condition node to keep only the items that matter, and pass those onward. This is the shape of most reporting and notification workflows: get the new orders, keep the ones over a threshold, send a message about each.
Pattern 2 — Fetch, then fetch details
Fetch a list, loop over it, and for each item make a second request to a detail endpoint using that item’s ID. This n8n http request node documentation notes that this is slower than fetching everything at once, but it is the standard approach when the list endpoint returns summaries and the detail endpoint returns the full record.
Pattern 3 — Send data from a trigger
Take data from a trigger — a form submission, a new row in a spreadsheet, a webhook — and POST it to an API to create a record in another system. This is the classic integration pattern, and the main work is mapping fields from the trigger’s data into the JSON body the API expects.
Pattern 4 — Keep two systems in sync
Fetch from one system, compare with the other, and create or update only what has changed. This pattern rewards care with pagination and error handling, because a sync that stops halfway can leave the two systems inconsistent. Running it on a schedule, with logging of what changed, makes it auditable.
Troubleshooting the Failures You Will Actually Meet
In this n8n http request node documentation, troubleshooting starts with matching the symptom to its likely cause.
| Symptom | Likely cause | Check first |
|---|---|---|
| 401 Unauthorized | Missing, expired, or wrong credentials | Credential in n8n, token expiry, correct account |
| 403 Forbidden | Credentials valid, permission missing | Scopes or permissions granted to the key or token |
| 404 Not Found | Wrong endpoint or ID | URL spelling, endpoint path, ID from an earlier node |
| 400 or 422 | Body or parameters do not match the API’s expectations | Required fields, data types, JSON formatting |
| 429 Too Many Requests | Rate limit reached | Wait and retry, add delays between requests |
| Timeout or connection error | Service slow, unreachable, or URL wrong | URL, network, whether the service itself is down |
| Empty or unexpected data | Response format differs from what later nodes expect | Inspect the raw response before the next node |
The single most useful debugging habit is to inspect the actual response before guessing. Run the node on its own, look at what came back — status code, headers, body — and compare it with what the API documentation says should come back.
Most HTTP Request problems reveal themselves in that comparison within a minute, while guessing at settings can burn an afternoon. This n8n http request node documentation therefore recommends inspecting the response first.
Frequently Asked Questions About This n8n http request node documentation
This n8n http request node documentation answers the questions new users ask most.
Do I need to know programming to use the HTTP Request node?
No, but you need to be comfortable reading API documentation and working with JSON at a basic level. You will not be writing a program, but you will be translating an API’s examples into the node’s fields, and that gets easier with each API you connect.
When should I use the HTTP Request node instead of a dedicated node?
When no dedicated node exists for the service or action, or when the dedicated node does not expose the option you need. If a dedicated node covers your use case, it will usually be quicker and handle edge cases for that service already.
How do I keep API keys safe in n8n?
Store them in n8n credentials, not in the node’s visible fields or in shared workflow exports. Credentials are stored separately and referenced by the node, so a workflow can be shared or exported without leaking the secret itself.
Why does my request work in a testing tool but fail in n8n?
Usually a small difference: a missing header, a different body format, or credentials that were set in the testing tool but not in the n8n credential. Compare the working request’s method, URL, headers, and body field by field with the node’s settings.
Can the HTTP Request node upload files?
Yes, for APIs that accept file uploads, typically using a multipart or binary body. The details depend on the API, so follow its documentation for the upload format, and test with a small file first.
What if the API I need has no documentation?
That is harder, but not always a dead end. Browser developer tools can reveal the requests a web app makes to its own API, and those requests can often be reproduced with the HTTP Request node. Treat undocumented APIs cautiously, though: they can change without notice, and using them may fall outside the service’s terms.
For readers following this n8n http request node documentation, more automation and digital-tool guides in the same style can be found in the practical explainers on Daily Orvix, and the tech how-to articles on Astronomy 101 cover related everyday software topics.
Read Also: HTTP Error 401: What It Means and How to Fix It
#n8n #HTTPRequest #Automation #APIs #WorkflowAutomation

Related Articles
192.168.1.254 Router Login Guide (2026 Guide)
A plain-English walkthrough for opening the 192.168.1.254 router login page, signing in with the details on…
Location of Area Code 609 (Complete Guide): Where Is 609 and What You Need to Know
Area code 609 is a New Jersey area code covering parts of the state including the…

What Is 4Download? Is It Safe? Everything You Need to Know (2026 Guide)
4Download promises free versions of expensive software, but the safety record is poor. This guide explains…